Thoughtful Engineering
An operator's notes on scaling systems, building platforms and teams, and how engineering changes with AI agents. Written from the production floor at Probo, Gojek and now KoshaX.
Cricket Scale
Sudden, spiky, event-driven traffic. How Probo stayed up when all of India opened the app at the same moment.
Relay: A Control Plane for Agent Work
Human approval, bounded briefs and context layers for supervising multi-agent software work.
Why I'm Building an AI Assistant in the Age of Giants
Google plays by different rules on Android. Why I'm building an assistant for India anyway.
When the CLI Felt Like Magic
Heroku, the AWS CLI, K9s and Claude Code: from exposing complexity to structuring it.
The Joy of Coding
I don't type most of my code anymore. The joy was never in the typing.
Software Engineering: Living With Uncertainty
Tools come and go. What compounds, what doesn't, and how to last in a career built on change.
Cricket Scale, Part 3 - The Not-So-Technical Grind
The biggest wins came from deleting APIs, trimming features and writing match-day playbooks.
Scaling with Karpenter: The Good and The Bad
Karpenter in 2023: nodes in 40 seconds instead of 2 minutes, 40% cheaper compute, and a lot of IAM pain.
Cricket Scale, Part 2 - Redis: A Silver Bullet With a Cost
Redis kept p99 under 100 ms at peak. It also hid our tech debt, until it didn't.
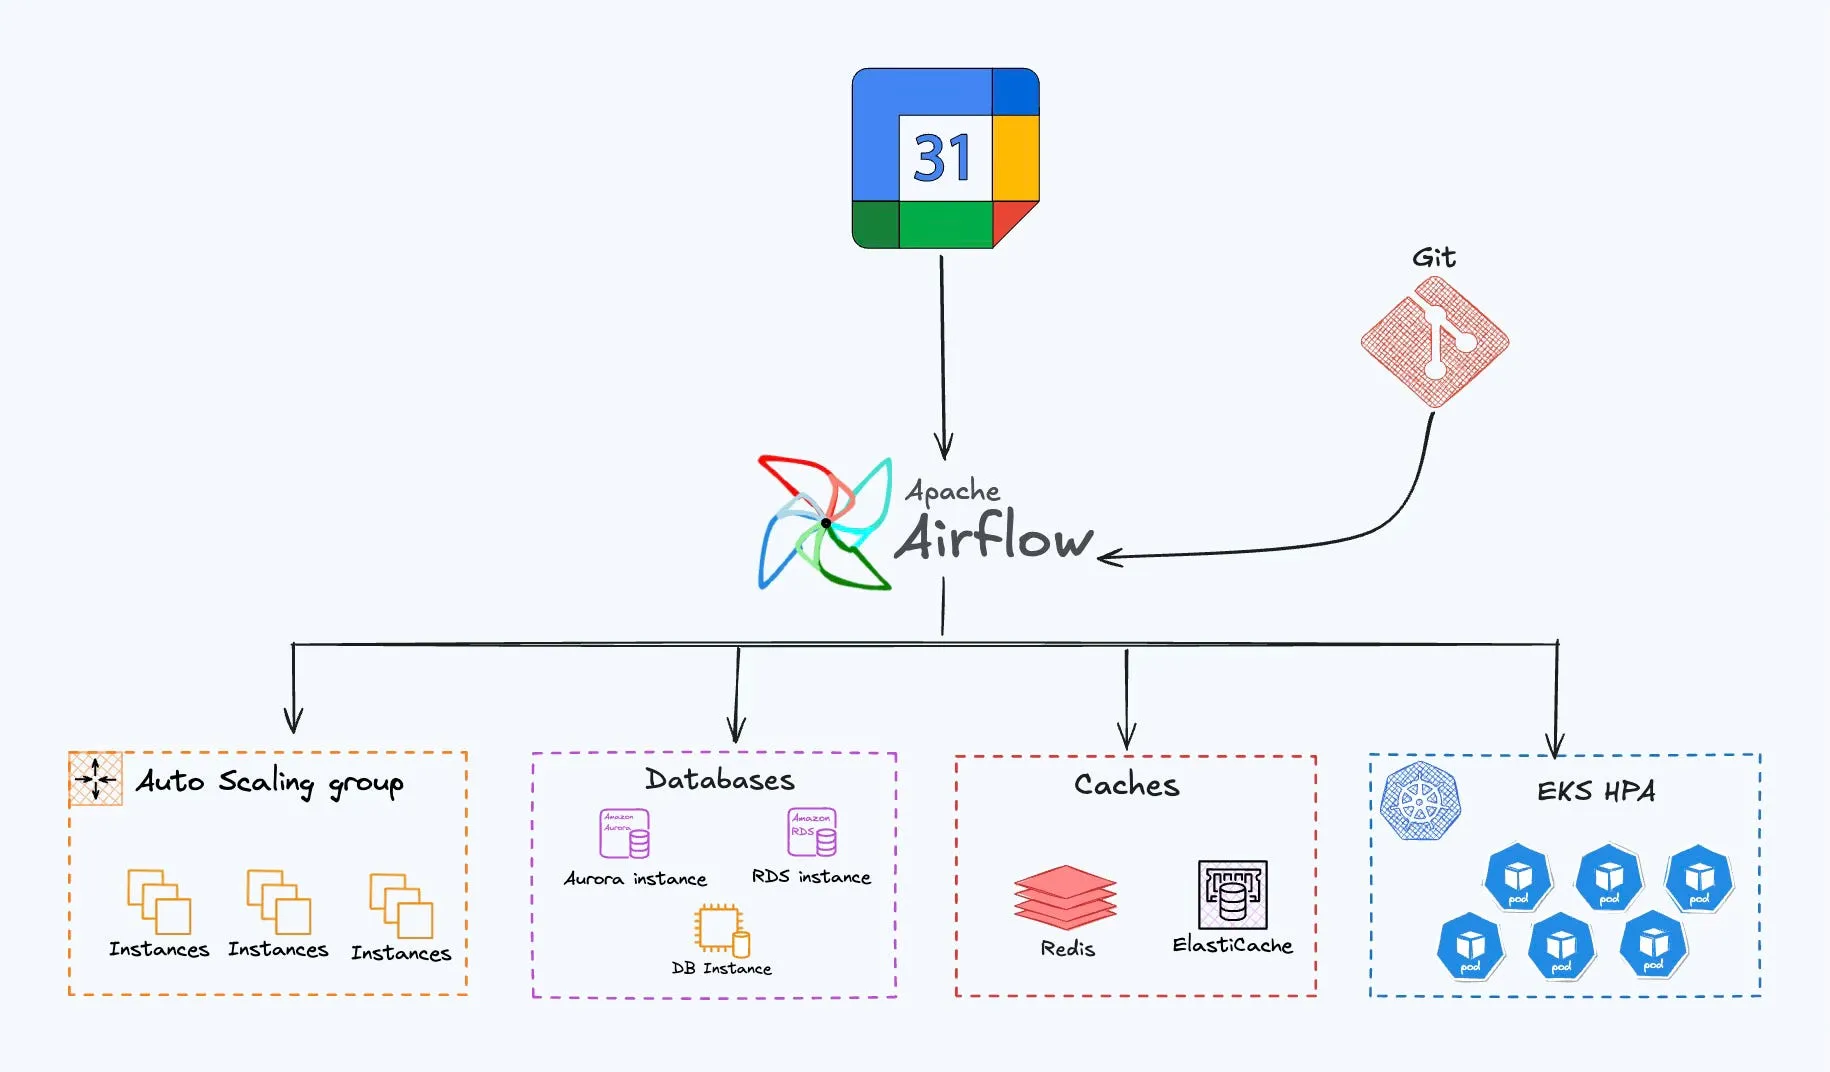
Scaler: our in-house scaling solution
A shared Google Calendar and an Airflow DAG let marketing schedule our infrastructure scaling.
Cricket Scale, Part 1 — EC2 vs Kubernetes
EC2 autoscaling was too slow for match-day spikes and Kubernetes wasn't ready. So we built a switcher.
Introducing the Cricket Scale Series
In India, a cricket match is a stress test. What we learned keeping Probo up through it.
Thinking in Systems: A Builder’s View
A fraud rule engine that paid off, a meme engine that didn't, and knowing the difference.
The Self-Aware Team
Teams that know the why, the ideal state and the trade-offs don't wait to be told what's next.
Democratizing Ownership: The Secret to Scalable Teams
Why the same few people always answered the alerts, and how we made reliability everyone's job.
Platform Teams and the Developer Experience Gap
Internal platforms succeed or fail on developer experience. Treat it as the core product.
Platform Teams: Avoid Becoming a Catch-All
Long feedback loops, becoming the bottleneck, becoming the dumping ground, and what helped.
How we scaled our Monolith to execute 250Mn+ trades in a day?
How about 30 engineers kept Probo on one monolith from zero to 250Mn+ trades a day, and what it cost us.